Apertus Claritas: An Inside View of Switzerland's Open Model
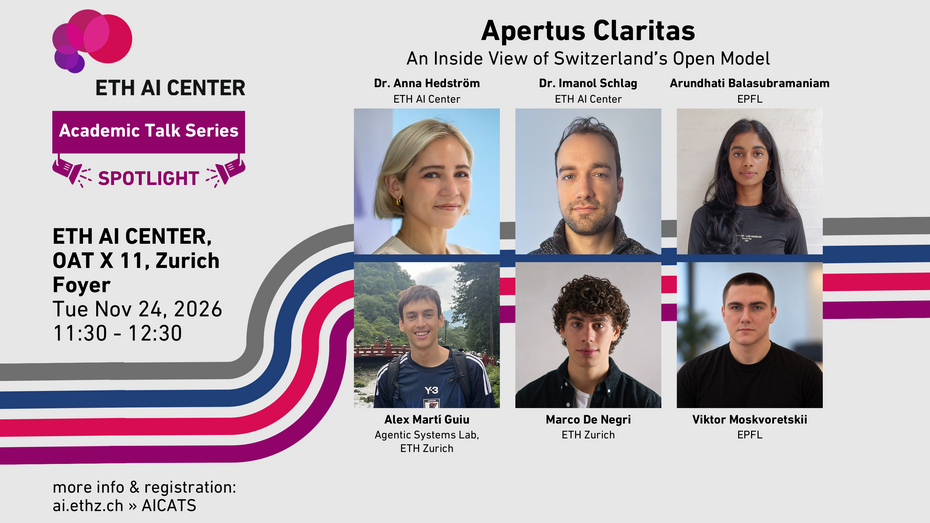
Apertus Claritas is a public home for interpretability and safety research on Apertus, Switzerland’s open multilingual model. From exploratory work and negative findings to published research, artefacts (https://apertus-claritas.org/artifacts) are reviewed and shared openly. After a short introduction by Anna Hedström and an update on Apertus by Imanol Schlag, several authors of Apertus Claritas artefacts give lightning talks on what they learned and solved when peeking inside Apertus.
The talks cover discoveries such as:
- Borrowed geometry: related languages share representations in Apertus and when ablating the high-resource direction, the low-resource output degrades.
- Emergent misalignment: polite stereotypes passing moderation filters trigger emergent misalignment in Apertus, with defenses improving safety but not the social bias.
- Degeneration probes: by training a lightweight probe on residual stream activations, repetitions in Apertus' answers can be detected online before the loop starts.
- Pre-training persona binding: an aligned assistant is built on a persona already formed in pre-training and that inserting constitution-grounded reflections improves alignment and jailbreak robustness while keeping capabilities intact.
Time is reserved at the end for questions and a discussion.